
Artificial intelligence is becoming increasingly accessible. Businesses can use many of the same frontier models, employees can ask similar questions, and competitors can build products on comparable underlying technology.
That raises a new question: if everyone has access to powerful AI, where will the competitive advantage come from?
One increasingly important answer is memory, not simply how intelligent an AI model is, but how effectively it can retain, retrieve and use the context accumulated around a person or business.
The next major advantage in artificial intelligence may therefore come from systems that understand what happened yesterday, what worked six months ago, what a customer prefers, how a company makes decisions and what an individual has learned over years.
In other words, the valuable asset may not be the AI model itself. It may be the memory surrounding it.
From Prompt Engineering to Context Engineering
For much of the generative-AI boom, attention centered on prompts. Users tried to find better ways of instructing models to obtain better answers.
That conversation is evolving.
Anthropic has described “context engineering” as an increasingly important discipline for AI agents. Instead of concentrating only on the wording of a prompt, context engineering considers what information should be available to an AI system when it needs to make a decision.
That context might include previous conversations, documents, customer interactions, company procedures, successful and unsuccessful decisions, preferences, project history and information retrieved from external systems.
The distinction is important.
Two companies could theoretically use the same underlying AI model and still receive dramatically different results if one has developed a rich, well-organized knowledge and memory system around it while the other is essentially starting from scratch every time.
Building a ‘Second Brain’ for AI
The idea was highlighted in a recent discussion about using AI inside businesses and content operations.
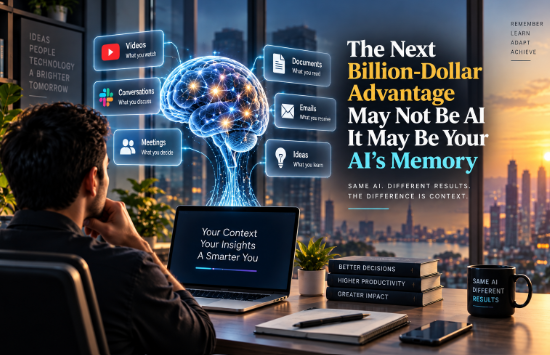
The entrepreneur described creating what he calls a “second brain” by collecting information from multiple sources. His system processes material from YouTube consumption, workplace conversations and team meetings, while also retaining useful information generated through interactions with AI systems.
Meetings, for example, can be transcribed and converted into information that can later be retrieved. AI conversations can similarly become part of a larger memory layer rather than disappearing into isolated chat sessions.
The objective is straightforward: when AI is asked to perform a task tomorrow, it should have access to relevant lessons from yesterday.
That could change the quality of the result dramatically.
Instead of asking an AI:
“Help me prepare for this meeting.”
A memory-enabled system could potentially understand who the person is, what was discussed previously, where disagreements occurred, what questions remain unanswered and which issues matter most to the user.
The model itself may be identical. The context surrounding it is not.
Why AI Memory Matters
The technical problem is well established.
Large language models operate with finite context. Even as context windows have expanded considerably, simply placing an enormous amount of information into a prompt does not automatically produce reliable long-term memory.
Researchers have consequently been experimenting with external memory architectures.
The MemGPT research project, developed by researchers associated with UC Berkeley, proposed managing different levels of memory in a manner inspired by computer operating systems. Its researchers demonstrated systems capable of maintaining information across extended conversations and working with documents larger than the underlying model’s immediate context window.
More recent research has continued to treat memory as a central problem for autonomous AI agents.
The 2026 Mem2ActBench research, for example, focuses on whether agents can actually use long-term memories to perform tasks, rather than merely retrieving previously stored facts.
Its results highlight an important limitation: current memory systems are still far from perfect.
So the opportunity is real, but the technology is not solved.
The Competitive Moat Could Be Proprietary Context
Consider two companies subscribing to the same powerful AI model.
Company A gives the model a generic instruction:
“Analyze why our sales declined.”
Company B connects its AI system to years of appropriately governed internal information: historical sales, advertising performance, product launches, pricing experiments, customer behavior, previous analyses and management decisions.
Company B’s AI could potentially reason from much richer organizational context.
The underlying intelligence may come from the same AI provider. But the institutional memory belongs to the company.
That is where an interesting competitive moat begins to emerge.
Companies have spent decades accumulating knowledge inside employees’ heads, emails, documents, Slack conversations, CRM systems, meeting notes and databases. Much of that information has historically been difficult to retrieve at exactly the moment a decision is being made.
AI agents combined with effective memory systems could make portions of that institutional knowledge continuously accessible.
AI That Learns How a Company Works
The transcript provides another useful example: an AI business-intelligence system connected to information including advertising, users, revenue and company databases.
Instead of manually moving between dashboards, a user could ask why return on investment declined and have an agent investigate multiple data sources.
But access to data alone is not enough.
The system also needs context explaining what the numbers mean, how revenue is attributed, which metrics matter and how the business operates.
That is the difference between giving AI information and giving AI institutional knowledge.
As companies build these layers, an AI agent could gradually become better adapted to one organization than another.
Personal AI Could Develop the Same Advantage
The concept extends beyond businesses.
Imagine using an AI assistant for five years.
Over that period, it could, subject to appropriate user control and privacy protections, understand the projects you have worked on, decisions you have made, writing you prefer, mistakes you want to avoid and goals you repeatedly pursue.
A new AI model might be technically more capable.
But an assistant carrying years of relevant personal context could potentially be more useful because it understands the user.
This is already becoming part of mainstream AI products. OpenAI, for example, said in June 2026 that it had developed a more scalable approach to synthesizing ChatGPT memory, specifically addressing challenges including freshness, correctness and long-term scalability.
The direction of travel is clear: AI assistants are increasingly being designed not merely to answer isolated questions but to maintain useful continuity over time.
But More Memory Is Not Always Better
There is an important catch.
Saving everything does not automatically make an AI smarter.
Old information can become inaccurate. Preferences change. Business strategies evolve. Contradictory memories can accumulate. Sensitive information creates privacy and security concerns. And irrelevant context can interfere with the information that actually matters.
This is why effective AI memory involves more than storage.
A useful system must determine what deserves to be remembered, what should be forgotten, what has become outdated and which memories are relevant to the task currently being performed.
Recent academic benchmarks reinforce this limitation. Research evaluating long-term-memory agents has found that contemporary systems can still struggle with complex memory retrieval and, crucially, with applying remembered information correctly when taking actions.
Memory is therefore not a solved feature that companies can simply switch on.
It is becoming an engineering problem of its own.
The Real AI Race May Be Moving Up the Stack
The first stage of the generative-AI race was largely about models.
Who had the smartest model? Who had the largest context window? Who could generate better text, images or code?
Those differences still matter.
But as powerful models become widely available through products and APIs, another layer of competition is emerging.
It is about who can give those models the best context.
The company with the most useful institutional memory could make better use of the same AI. The creator whose AI understands years of audience data could make better decisions than someone beginning with a blank prompt. The professional whose assistant understands years of work could potentially accomplish more than someone using the same underlying model without that history.
The model provides intelligence.
Memory provides continuity.
And context determines how effectively that intelligence can be applied.
That is why the next billion-dollar advantage in artificial intelligence may not belong exclusively to whoever builds the smartest model.
It may belong to whoever builds the best memory around it.